Vector Databases Explained: Why AI Search Works Differently From Keyword Search
Traditional search looks for words. AI search increasingly looks for meaning. That difference is why vector databases have become an important part of modern retrieval systems, recommendation engines and retrieval-augmented generation. Instead of storing only text that can be matched by keywords, a vector system stores numerical representations called embeddings and searches for items that are close to one another in that mathematical space.
Table of Contents
01 What It Is
A vector database is a system designed to store, index and search high-dimensional vectors. In AI applications, those vectors often come from an embedding model that converts text, images or other content into arrays of numbers.
The numbers are not meaningful to a person by themselves. Their value comes from the geometry: items with similar meaning tend to be represented closer together according to a similarity metric. A search for “cheap places to stay near an airport” can therefore retrieve content about “budget airport hotels” even if the exact words do not match.
That is different from classic keyword search, which is excellent at exact names, product codes, quotations and rare terms. Vector search is strongest when semantic similarity matters. Many real systems combine both approaches rather than treating one as a replacement for the other.
02 How It Works
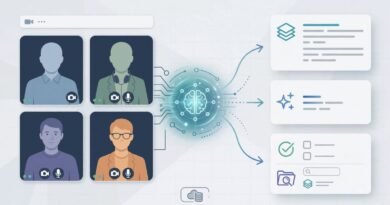
The process begins with embeddings. Documents are split into useful chunks, each chunk is passed through an embedding model, and the resulting vector is stored alongside metadata such as document name, date, permissions or category.
When a user searches, the query is converted into an embedding using a compatible model. The system then looks for stored vectors that are nearest to the query vector. Google’s machine-learning documentation describes retrieval in embedding space as a nearest-neighbor problem: find the items whose embeddings are closest to the query.
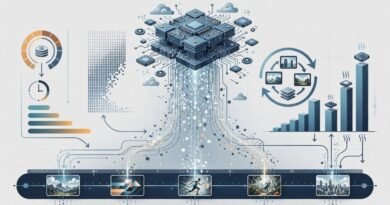
For small datasets, a system could compare the query with every stored vector. At scale, that becomes expensive, so vector systems use indexes and approximate nearest-neighbor techniques to retrieve strong candidates quickly without exhaustively scoring every item.
Metadata filters are also important. A company may want semantic similarity but only among documents the current user is permitted to access, or only among records from a specific country, product line or date range.
03 Why It Matters
Vector search lets applications retrieve relevant information even when users phrase a question differently from the source document. That is especially useful for natural-language queries, where people rarely know the exact wording stored in a knowledge base.
It also forms a common retrieval layer for RAG systems. The model does not need every company document stuffed into its prompt. Instead, the retrieval system finds a small set of relevant passages and provides them as context for the answer.
This can improve efficiency and relevance, but it does not guarantee truth. The vector database can return a semantically similar passage that is outdated, incomplete or about the wrong entity. Retrieval quality is therefore part of overall AI reliability, not a substitute for verification.
That reliability-versus-cost trade-off is also part of the wider AI economics Earnyx covers in its guide to deciding how much an AI tool is worth: infrastructure is valuable only when it improves a workflow enough to justify its operational cost.
04 What It Means for You
For users, vector search is why an AI-powered search box may understand concepts rather than only literal terms. You can ask a question in conversational language and still retrieve documents that use different wording.
For businesses, the main design choices include chunk size, embedding model, metadata, access controls and the search strategy. Poor chunking can split important context. Weak metadata can make filtering difficult. Missing permission checks can create a serious data-security problem if the system retrieves information a user should not see.
For developers, hybrid search is often worth considering. Keyword ranking can preserve exact-match strengths while vector similarity adds semantic recall. A reranking step can then score the retrieved candidates more carefully before they are passed to the model.
05 Numbers + Context
Vectors can contain hundreds or thousands of dimensions depending on the embedding model. More dimensions do not automatically mean better search; what matters is whether the embedding model represents the relationships your application needs.
Retrieval systems are usually evaluated with metrics such as recall at K, precision at K, ranking quality and task-level answer accuracy. If the correct source rarely appears in the top retrieved results, improving the language model will not fix the underlying retrieval problem.
At large scale, approximate nearest-neighbor indexing trades a small amount of exactness for much faster retrieval. The practical goal is not mathematical perfection. It is getting the right evidence into the candidate set quickly enough for the application to use it.
06 Earnyx Takeaway
Vector databases matter because they let software search by semantic similarity rather than relying only on literal words. That makes them a natural fit for AI assistants, recommendation systems and RAG.
But “semantic” does not mean “correct.” Good AI search still needs exact-match support, sensible chunking, metadata filters, permission controls and evaluation. A vector database is the retrieval engine—not the judge of whether the retrieved information is current, authorized or true.