AI Model Routing Explained: Why Apps Switch Between Models and Use Fallbacks
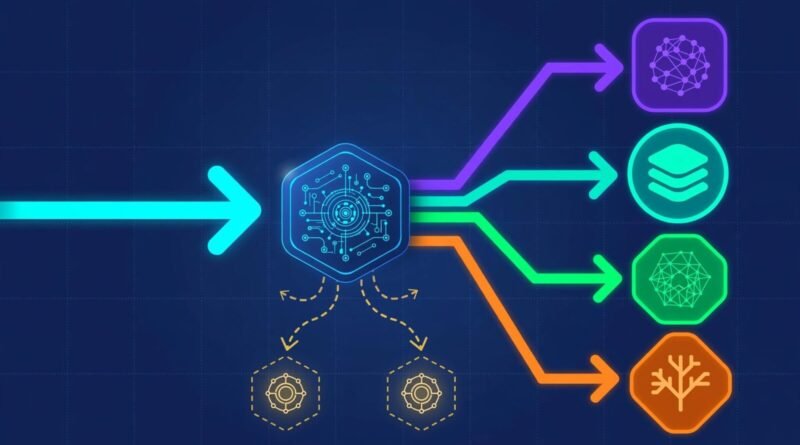
Many AI apps no longer rely on one model for every request. A simple rewrite may go to a fast, inexpensive model, while a difficult coding or reasoning task goes to a more capable one. If the preferred model is unavailable, the app may automatically switch to another. This behind-the-scenes decision process is called model routing.
Table of Contents
01 What It Is
AI model routing is the logic that chooses which model should handle a particular request. The router can consider factors such as task type, complexity, cost, latency, context length, required tools, data location or current model availability.
A routing system might send image-heavy tasks to a multimodal model, routine classification to a smaller model and complex reasoning to a larger one. It may also use a fallback chain: if the first model fails, times out or reaches a rate limit, another model gets the request.
The user may never see this. One product name can sit above several models from the same provider—or even models from different providers. That means the behavior of an AI application can depend not only on the quality of its best model, but also on how intelligently the product decides when to use it.
02 How It Works
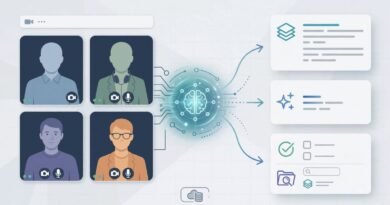
Routing can be rule-based or learned. A simple system can inspect obvious signals: if a request contains an image, use a vision-capable model; if the prompt is short and low-risk, use the low-cost model; if a tool requires a particular provider, use that provider.
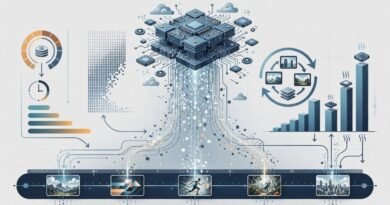
More advanced routers can classify the request first, estimate difficulty or compare candidate models. Some systems may start with a cheaper model and escalate only when quality checks fail. Others route according to service health so that an outage at one provider does not stop the application entirely.
Fallbacks are related but slightly different. Routing chooses the preferred path. A fallback defines what happens when that path cannot complete the job. Good fallbacks preserve required features and safety controls rather than merely picking any model that responds.
03 Why It Matters
The economics are powerful. Premium models can cost substantially more per token than smaller models, especially for output. Sending every request to the most capable option may deliver high quality, but it can waste money on tasks that do not need it. Routing lets developers reserve expensive inference for the requests where it creates real value.
That matters as companies scrutinize AI costs. Earnyx has covered how business AI spending is beginning to face tighter budget pressure. Model routing is one of the practical ways companies can control those costs without abandoning AI altogether.
Routing also affects reliability. If an application depends on one model endpoint, a provider outage or rate-limit problem can become an application outage. A well-tested fallback can keep basic functionality running. But switching models can also change tone, formatting, reasoning quality or tool behavior, so resilience comes with consistency challenges.
04 What It Means for You
For users, routing explains why the same AI product can sometimes feel faster, slower or slightly different from one request to the next. That variation does not necessarily mean the company secretly “downgraded” every user. The request may have taken a different path based on complexity or capacity.
For businesses buying AI software, it is worth asking whether the vendor discloses which models are used for sensitive workflows, whether customer data can move between providers, and what happens during fallback. A secondary model may have different data-retention, regional or compliance properties.
For developers, the safest approach is to evaluate the full routed system rather than only the flagship model. Test whether the router sends difficult tasks to the right model, whether fallback outputs still satisfy schemas, and whether cost savings are worth any quality loss.
05 Numbers + Context
The right routing metric is not simply “percentage sent to the cheap model.” Useful measurements include cost per successful task, median and tail latency, escalation rate, fallback frequency, task success rate and quality by route. A router that cuts inference cost by half but doubles human rework is not actually cheaper.
Modern providers expose large differences in model capability, latency and price. That creates the economic space for routing. The exact numbers change frequently, which is why routing logic should use current provider pricing and live evaluation results rather than hard-coded assumptions about which model is always best.
06 Earnyx Takeaway
Model routing is becoming one of the invisible layers that determines how AI products feel and how much they cost. The smartest architecture is rarely “use the biggest model for everything.” It is “use the least expensive model that reliably completes this specific job, and escalate when necessary.”
But routing only works when it is measured. Cheap models, premium models and fallbacks should all be tested against the same real-world tasks. Otherwise a company can save money on inference while quietly paying for the difference in errors, retries and human correction.